About the HALCON deep learning model🔗
This page explains the general concept of the deep learning (DL) model in HALCON and the data handling.
A deep learning model in HALCON is an internal representation of a deep neural network. Each deep neural network has an architecture defining its function, that is, the tasks it can be used for.
There can be several possible network architectures for one functionality. Currently, networks for the following functionalities are implemented in HALCON as model:
-
Classification, including Continual Learning and multi-label classification
Each functionality is identified by its unique model type.
More Info
- For more information about the specific workflow, data requirements, and validation measures, see the corresponding pages.
- For more information about deep learning in general, see the deep learning overview page.
About the general data🔗
Deep Learning applications have different types of data to be distinguished. Roughly spoken these are: The raw images with possible annotations, data preprocessed in a way suitable for the model, and output data.
Before the different types of data and the entries of the specific dictionaries are explained, we take a look how the data is connected. Symbols and colors refer to the schematic overviews given below (training: Figure 1, inference: Figure 2).
- Training and evaluation
-
In brief, the data structure for training or evaluation starts with the raw images and their ground truth annotations (gray frames). With the read data, the following dictionaries are created:
- The dictionary
DLDataset(red) serves as database and refers to a specific dictionary (yellow) for every input image. - The dictionary
DLSample(orange) contains the data for a sample in the way the network can process it. - A batch of
DLSampleis handed to the model inDLSampleBatch. - For training, the training results (for example, loss values) are returned in the dictionary
DLTrainResult(light blue). - For evaluation,
DLResultBatchis returned, a tuple of dictionariesDLResult(dark blue), one for every sample. They are needed to obtain the evaluation resultsEvaluationResult.
The most important steps concerning modifying or creating a dictionary are:
- Reading the raw data (symbol: paper with arrow)
- Preprocessing the data (symbol: cogs)
- Training (symbol: transparent brain in an arc)
- Evaluating the model (symbol: graph)
-
Evaluating a sample (symbol: magnifying glass)
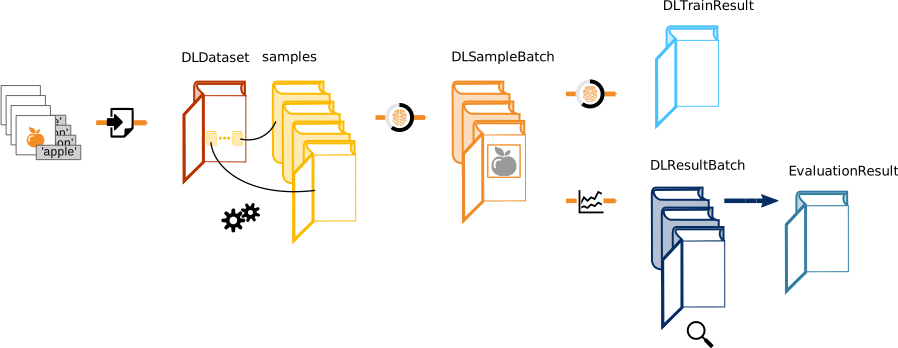
Figure 1. Schematic overview of the data structure during training and evaluation
- The dictionary
- Inference
-
For inference, no annotations are needed.
- Thus, the data structure starts with the raw images (gray frames).
- The dictionary
DLSample(orange) contains the data for a sample in the way the network can process it. - The results for a sample are returned in a dictionary
DLResult(dark blue).
The most important steps concerning modifying or creating a dictionary:
- Reading the raw data (symbol: paper with arrow)
- Preprocessing the data (symbol: cogs)
- Inference (symbol: brain in a circle)
-
Evaluating a sample (symbol: magnifying glass)
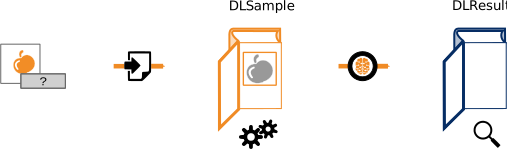
Figure 2. Schematic overview of the data connection during inference
Details about the dictionaries🔗
For the model to process the data, the data needs to follow certain conventions about what is needed and how it is given to the model. As visible from the figures above, in HALCON the data is transferred using dictionaries.
In the following, we explain the involved dictionaries, how they can be created, and their entries.
Training and evaluation input data🔗
The dataset consists of images and corresponding information. They have to be provided in a way the model can process them. For more information about image requirements, see Images below.
The information about the images and the dataset is represented in a dictionary DLDataset, which serves as a database.
More precisely, it stores the general information about the dataset and the dictionaries of the individual samples collected under the key samples.
When the actual image data is needed, a dictionary DLSample is created (or read if it already exists) for each image required.
The relation of these dictionaries is illustrated in the figure below.
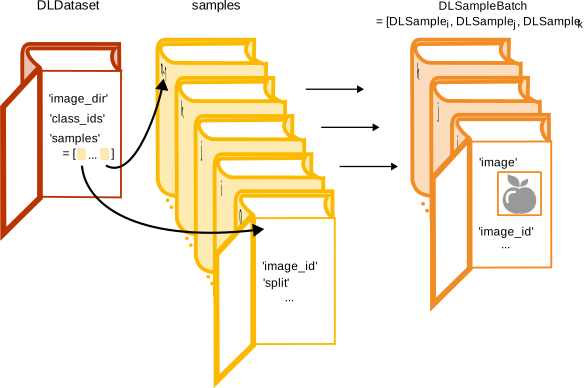
Figure 3. Schematic illustration of the different dataset dictionaries used for training and evaluation.
For visibility purpose, only few entries are registered and BatchSize is set to three.
In this example, we have \(n\) samples.
Of these, three samples are chosen randomly: i,j, and k.
The corresponding dictionaries DLSample are created and joined in the tuple DLSampleBatch.
The following sections describe these dictionaries.
DLDataset🔗
The dictionary DLDataset serves as a database and is used by the training and evaluation procedures.
It stores general information about the dataset and collects the dictionaries of the individual samples.
Hence, iconic data is not included in DLDataset but the paths to the respective images.
It is not necessary for the model, but we highly recommend creating it.
This dictionary is either created directly when labeling your data using the MVTec Deep Learning Tool, available from the MVTec website, or it is created by one of the following method-specific procedures:
-
3D Gripping Point Detection:
read_dl_dataset_3d_gripping_point_detection -
Anomaly detection, Global Context Anomaly Detection:
read_dl_dataset_anomaly -
Classification:
read_dl_dataset_classification -
Deep OCR – detection component:
read_dl_dataset_ocr_detection -
Deep OCR – recognition component:
read_dl_dataset_ocr_recognition -
Object detection with
'instance_type'='rectangle1':read_dl_dataset_from_coco -
Semantic segmentation:
read_dl_dataset_segmentation
For the requirements on the data in order to use these procedures, see the respective procedure documentation.
If you create DLDataset in another way, it has to contain at least the entries that are not marked with a footnote number in Table 1 below.
During the preprocessing of your dataset, the respective procedures include the further entries of the dictionary DLDataset.
Entry |
Model |
Meaning | Format |
|---|---|---|---|
image_dir |
any | Common base path to all images | string |
dlsample_dir1 |
any | Common base path of all sample files (if present) | string |
class_names |
any except OCR-R | Names of all classes that are to be distinguished | tuple of strings |
class_ids |
any except OCR-R | IDs of all classes that are to be distinguished (range: 0-65534) | tuple of integers |
preprocess_param |
any | All parameter values used during preprocessing | dictionary |
samples |
any | Collection of sample descriptions | tuple of dictionaries |
normals_dir |
3D-GPD | Common base path of all normals images (optional) | string |
xyz_dir |
3D-GPD | Common base path of all XYZ-images | string |
orig_3d_model |
3D-PE | 3D CAD object model | string |
anomaly_dir |
AD, GC-AD | Common base path of all anomaly regions (regions indicating anomalies in the image) | string |
class_weights1 |
CL, SE | Weights of the different classes | tuple of reals |
segmentation_dir |
SE, 3D-GPD | Common base path of all segmentation images | string |
samples🔗
The DLDataset key samples gets a tuple of dictionaries as value, one for each sample in the dataset.
These dictionaries contain the information concerning an individual sample of the dataset.
Depending on the model type, this dictionary can have the entries described in Table 2 below.
Entry |
Model |
Meaning | Format |
|---|---|---|---|
image_file_name |
any | File name of the image and its path relative to image_dir |
string |
image_id |
any | Unique image ID (encoding format: UINT8) | integer |
split2 |
any | Specifies the assigned split subset ('train', 'validation', 'test') |
string |
dlsample_file_name3 |
any | File name of the corresponding dictionary DLSample and its path relative to dlsample_dir |
string |
normals_file_name |
3D-GPD | Optional. File name of the normals image and its path relative to normals_dir |
string |
segmentation_file_name |
3D-GPD, SE | File name of the ground truth segmentation image and its path relative to segmentation_dir |
string |
xyz_file_name |
3D-GPD | File name of the XYZ-image and its path relative to xyz_dir |
string |
anomaly_file_name |
AD, GC-AD | Optional. Path to region files with ground truth annotations (relative to anomaly_dir) |
string |
anomaly_label |
AD, GC-AD | Ground truth anomaly label on image level (in the form of class_names) |
string |
image_label_id |
CL | Ground truth label for the image (in the form of class_ids) |
tuple of integers |
image_label_ids |
MLC | Ground truth labels for the image (in the form of class_ids) |
tuple of integers |
image_id_origin |
OCR-R | ID of the original image the sample was extracted from | integer |
word |
OCR-D, OCR-R | Ground truth word | string |
bbox_label_id |
OD, OCR-D | Ground truth labels for the bounding boxes (in the form of class_ids) |
tuple of integers |
bbox_row14 |
OD:R1 | Ground truth bounding boxes: upper left corner, row coordinate | tuple of reals |
bbox_col14 |
OD:R1 | Ground truth bounding boxes: upper left corner, column coordinate | tuple of reals |
bbox_row24 |
OD:R1 | Ground truth bounding boxes: lower left corner, row coordinate | tuple of reals |
bbox_col24 |
OD:R1 | Ground truth bounding boxes: lower left corner, column coordinate | tuple of reals |
coco_raw_annotations |
OD:R1 | Optional. Contains a dictionary with all raw COCO annotation information for each bbox_label_id within this image |
tuple of dictionaries |
bbox_row4 |
OCR-D, OCR-R, OD:R2 | Ground truth bounding boxes: center point, row coordinate | tuple of real |
bbox_col4 |
OCR-D, OCR-R, OD:R2 | Ground truth bounding boxes: center point, column coordinate | tuple of real |
bbox_phi4 |
OCR-D, OCR-R, OD:R2 | Ground truth bounding boxes: angle φ | tuple of real |
bbox_length14 |
OCR-D, OCR-R, OD:R2 | Ground truth bounding boxes: half length of edge 1 | tuple of reals |
bbox_length24 |
OCR-D, OCR-R, OD:R2 | Ground truth bounding boxes: half length of edge 2 | tuple of reals |
visibility |
OD | Fractional visibility of bounding boxes | tuple of reals |
mask |
3D-PE, IS | Ground truth mask marking the instance regions | tuple of regions |
camera_parameter |
3D-PE | Camera parameter for the image | tuple of HALCON camera parameters |
pose |
3D-PE | Poses of the objects in each bounding box | tuple of HALCON poses |
DLSample🔗
The dictionary DLSample serves as input for the model.
UNCLEAR – who is “they”? –> For a batch, they are handed over as the entries of the tuple DLSampleBatch for apply_dl_model or train_dl_model_batch.
They are created out of DLDataset for every sample by the procedure gen_dl_samples followed by preprocess_dl_samples.
preprocess_dl_samples will update the corresponding DLSample dictionary.
If preprocessing is done using the standard procedure preprocess_dl_dataset, the preprocessed samples are stored on the file system.
Afterwards, they need to be retrieved with the procedure read_dl_samples.
DLSample contains the preprocessed image and, in case of training and evaluation, all ground truth annotations.
Depending on the model type, this dictionary can have the entries described in Table 3 below.
Entry |
Model |
Meaning | Format |
|---|---|---|---|
anomaly_ground_truth |
AD, GC-AD | Anomaly image or region, read from anomaly_file_name |
image or region |
anomaly_label |
AD, GC-AD | Ground truth anomaly label on image level (in the form of class_names) |
string |
anomaly_label_id |
AD, GC-AD | Ground truth anomaly label ID on image level (in the form of class_ids) |
integer |
bbox_label_id |
OD | Ground truth labels for the image part within the bounding box (in the form of class_ids) |
tuple of integers |
bbox_row14 |
OD:R1 | Ground truth bounding boxes: upper left corner, row coordinate | tuple of reals |
bbox_col14 |
OD:R1 | Ground truth bounding boxes: upper left corner, column coordinate | tuple of reals |
bbox_row24 |
OD:R1 | Ground truth bounding boxes: lower left corner, row coordinate | tuple of reals |
bbox_col24 |
OD:R1 | Ground truth bounding boxes: lower left corner, column coordinate | tuple of reals |
bbox_row4 |
OCR-D, OD:R2 | Ground truth bounding boxes: center point, row coordinate | tuple of reals |
bbox_col4 |
OCR-D, OD:R2 | Ground truth bounding boxes: center point, column coordinate | tuple of reals |
bbox_phi4 |
OCR-D, OD:R2 | Ground truth bounding boxes: angle φ | tuple of reals |
bbox_length14 |
OCR-D, OD:R2 | Ground truth bounding boxes: half length of edge 1 | tuple of reals |
bbox_length24 |
OCR-D, OD:R2 | Ground truth bounding boxes: half length of edge 2 | tuple of reals |
image |
any | Input image | image |
image_label_id |
CL | Ground truth label for the image (in the form of class_ids) |
integer |
image_label_ids |
MCL | Ground truth labels for the image (in the form of class_ids) |
tuple of integers |
mask |
3D-PE, IS | Ground truth mask marking the instance regions | tuple of regions |
normals |
3D-GPD | 2D mappings (3-channel image) | image |
segmentation_image |
SE, 3D-GPD | Image with the ground truth segmentations, read from segmentation_file_name |
image |
weight_image5 |
SE | Image with the pixel weights | image |
target_orientation |
OCR-D | Orientation target image for the word orientation | image |
target_text |
OCR-D | Text target image for the character detection | image |
target_link |
OCR-D | Link target image for the connection of detected character centers to a connected word | image |
target_weight_orientation |
OCR-D | Weight with respect to target_orientation |
image |
target_weight_link |
OCR-D | Weight with respect to target_link |
image |
target_weight_text |
OCR-D | Weight with respect to `target_text | image |
word |
OCR-D, OCR-R | Ground truth word | string |
x |
3D-GPD | X-image (values need to increase from left to right) | image |
y |
3D-GPD | Y-image (values need to increase from top to bottom) | image |
z |
3D-GPD | Z-image (values need to increase from points close to the sensor to far points6) | image |
camera_parameter |
3D-PE | Camera parameter for the image | tuple of HALCON camera parameter |
pose |
3D-PE | Poses of the objects in each bounding box | tuple of HALCON poses |
width_orig |
3D-PE | Original width of the bounding boxes | tuple of reals |
height_orig |
3D-PE | Original height of the bounding boxes | tuple of reals |
Inference input data🔗
The inference input data consists of a single DLSample dictionary or a tuple of such.
In contrast to training and evaluation, only the keys described in Table 4 are used:
Entry |
Model |
Meaning | Format |
|---|---|---|---|
image |
any | Input image | image |
normals |
3D-GPD | 2D mappings (3-channel image) | image |
x |
3D-GPD | X-image (values need to increase from left to right) | image |
y |
3D-GPD | Y-image (values need to increase from top to bottom) | image |
z |
3D-GPD | Z-image (values need to increase from points close to the sensor to far points7) | image |
For more information about the image requirements, see Images below.
For the inference, such a dictionary containing only the image data can be created using the procedure gen_dl_samples_from_images or, for 3D Gripping Point Detection, gen_dl_samples_3d_gripping_point_detection.
These dictionaries can be passed one at a time or within a tuple DLSampleBatch.
Training output data🔗
The training output data is given in the dictionary DLTrainResult.
Its entries depend on the model and thus on the operator used.
For more information, see the documentation of the corresponding operator.
- 3D-GPD, 3D-PE, CL, MLC, OCR-D, OCR-R, GC-AD, OD, SE
-
The operator
train_dl_model_batchreturns-
total_loss -
possible further losses included in your model
-
- AD
-
The operator
train_dl_model_anomaly_datasetreturns-
final_error -
final_epoch
-
Inference and evaluation output data🔗
As output from the operator apply_dl_model, the model will return a dictionary DLResult for each sample.
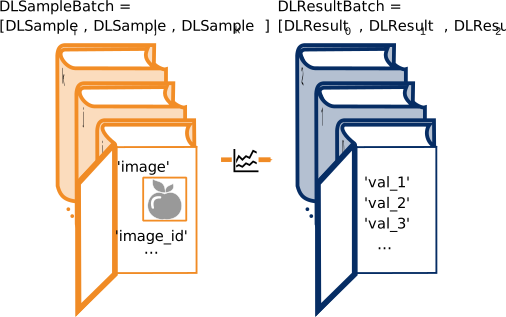
An illustration is given in the figure below.
The evaluation is based on these results and the annotations.
Evaluation results are stored in the dictionary EvaluationResult.
  |
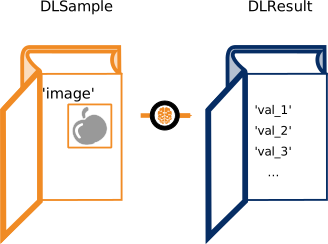  |
Figure 4. Schematic illustration of the dictionaries serving as model input:
Evaluation: DLSample includes the image as well as information about the image and its content.
This data serves as basis for the evaluation.
For visibility purposes, BatchSize is set to three (containing the randomly chosen samples i, j, and k) and only few entries are registered.
Inference: DLSample contains only the image.
These dictionaries can be passed one at a time or within a tuple.
Note
For models of type 3D-PE, inference and evaluation are not performed as described above. For more information about how to use Deep 3D Matching inference, see 3D Matching > Deep 3D Matching.
Depending on the model type, the dictionary DLResult can have the entries described in Table 5 below.
Entry |
Model |
Meaning | Format |
|---|---|---|---|
gripping_confidence |
3D-GPD | Image, containing raw, uncalibrated confidence values for every point in the scene | image |
gripping_map |
3D-GPD | Binary image, indicating for each pixel of the scene whether the model predicted a gripping point (pixel value = 1.0) or not (0.0) |
image |
anomaly_image |
AD, GC-AD | Single channel image; gray values are scores, indicating how likely the corresponding pixel in the input image belongs to an anomaly | image |
anomaly_image_combined |
GC-AD | Single channel image; gray values are scores, indicating how likely the corresponding pixel in the input image belongs to an anomaly. Calculated by combining the 'local' and 'global' subnetworks of the model |
image |
anomaly_image_global |
GC-AD | Single channel image; gray values are scores, indicating how likely the corresponding pixel in the input image belongs to an anomaly. Calculated by the 'global' subnetwork of the model |
image |
anomaly_image_local |
GC-AD | Single channel image; gray values are scores, indicating how likely the corresponding pixel in the input image belongs to an anomaly. Calculated by the 'local' subnetwork of the model |
image |
anomaly_score |
AD, GC-AD | Anomaly score on image level calculated from anomaly_image |
real |
anomaly_score_local |
GC-AD | Anomaly score on image level calculated from anomaly_image_local |
real |
anomaly_score_global |
GC-AD | Anomaly score on image level calculated from anomaly_image_global |
real |
classification_class_ids |
CL | Inferred class ids for the image sorted by confidence values | tuple of integers |
classification_class_names |
CL | Inferred class names for the image sorted by confidence values | tuple of strings |
classification_confidences |
CL | Confidence values of the image inference for each class | tuple of reals |
class_ids |
MLC | Inferred class ids for the image sorted by confidence values | tuple of integers |
class_names |
MLC | Inferred class names for the image sorted by confidence values | tuple of strings |
confidences |
MLC | Confidence values of the image inference for each class | tuple of reals |
selected_class_ids |
MLC | Class ids for the image selected by the confidence threshold(min_confidence) |
tuple of integers |
selected_class_names |
MLC | Class names for the image selected by the confidence threshold (min_confidence) |
tuple of strings |
selected_confidences |
MLC | Confidence values of the image selected by the confidence threshold for each class | tuple of reals |
char_candidates |
OCR-R | Candidates for each character of the word and their confidences | tuple of dictionaries |
word |
OCR-R | Recognized word | string |
score_maps |
OCR-D | Scores given as image with four channels8 | image |
words |
OCR-D | Dictionary containing entries9 | dictionary with tuples of reals and strings |
word_boxes_on_image |
OCR-D | Dictionary with the word localization, coordinate system of the preprocessed images placed in image10 |
dictionary with tuples of reals |
word_boxes_on_score_maps |
OCR-D | Dictionary with the word localization on the coordinate system of the score images placed in score_maps10 |
dictionary with tuples of reals |
bbox_class_id |
OD | Inferred class for the bounding box (in the form of class_ids) |
tuple of integers |
bbox_class_name |
OD | Name of the inferred class for the bounding box | tuple of strings |
bbox_confidence |
OD | Confidence value of the inference for the bounding box | tuple of reals |
bbox_row14 |
OD:R1 | Inferred bounding boxes: upper left corner, row coordinate | tuple of reals |
bbox_col14 |
OD:R1 | Inferred bounding boxes: upper left corner, column coordinate | tuple of reals |
bbox_row24 |
OD:R1 | Inferred bounding boxes: lower right corner, row coordinate | tuple of reals |
bbox_col24 |
OD:R1 | Inferred bounding boxes: lower right corner, row coordinate | tuple of reals |
bbox_row4 |
OD:R2 | Inferred bounding boxes: center point, row coordinate | tuple of reals |
bbox_col4 |
OD:R2 | Inferred bounding boxes: center point, column coordinate | tuple of reals |
bbox_phi4 |
OD:R2 | Inferred bounding boxes: angle φ | tuple of reals |
bbox_length14 |
OD:R2 | Inferred bounding boxes: half length of edge 1 | tuple of reals |
bbox_length24 |
OD:R2 | Inferred bounding boxes: half length of edge 2 | tuple of reals |
mask |
IS | Inferred mask marking the instance regions | tuple of regions |
mask_probs |
IS | Image with the confidence values of the inferred mask | image |
segmentation_image |
SE | Image with the segmentation result | image |
segmentation_confidence |
SE | Image with the confidence values of the segmentation result | image |
Image requirements🔗
Regardless of the application, the network poses requirements on the images.
The specific values depend on the network itself and can be queried using get_dl_model_param.
To fulfill these requirements, you may have to preprocess your images.
Standard preprocessing of the entire dataset and hence also the images is implemented in preprocess_dl_samples.
In case of custom preprocessing, this procedure offers guidance on the implementation.
More Info
For a further explanation of the output values, see the page of the respective method, for example, Deep Learning > Semantic Segmentation.
-
The procedure
split_dl_datasetaddssplit. ↩ -
The procedure
preprocess_dl_samplesaddsdlsample_file_name. ↩ -
Used coordinates: pixel centered, subpixel-accurate coordinates ↩↩↩↩↩↩↩↩↩↩↩↩↩↩↩↩↩↩↩↩↩↩↩↩↩↩↩
-
Created by the procedure
gen_dl_segmentation_weights↩ -
For example, if the data is given in the camera coordinate system ↩
-
For example, if the data is given in the camera coordinate system ↩
-
Score per channel:
- Character score: score for the character detection
- Link score: score for the connection of detected character centers to a connected word
- Orientation 1: sine component of the predicted word orientation
- Orientation 2: cosine component of the predicted word orientation
-
Entries are tuples with a value for every found word:
row: localized word: center point, row coordinatecol: localized word: center point, column coordinatephi: localized word: angle φlength1: localized word: half length of edge 1length2: localized word: half length of edge 2line_index: line index of localized word if'detection_sort_by_line'set to'true'
-
Entries are tuples with a value for every found word:
row: localized word: center point, row coordinatecol: localized word: center point, column coordinatephi: localized word: angle φlength1: localized word: half length of edge 1length2: localized word: half length of edge 2